 3AM Marketer
MoE Training Handbook: Parallelism and Throughput
A technical handbook on balancing expert parallelism, memory allocation, and communication overhead in large-scale MoE model training.
MegaScale-MoE achieved 1.41 million tokens per second when training a 352 billion parameter mixture of experts model across 1,440 NVIDIA Hopper GPUs, yielding a 1.88x throughput speedup over standard Megatron-LM. Configuring large-scale Mixture of Experts (MoE) training requires balancing memory distribution against interconnect saturation, as widening expert parallelism trades per-device memory pressure for collective communication overhead.1
Decoupling compute cost from parameter count
Sparse MoE architectures scale model capacity without a proportional expansion in compute requirements. For example, Mixtral 8x7B maintains 45 billion total parameters with 8 experts per MLP layer, yet the compute required for a single forward pass equals that of a 14 billion parameter dense model. The architecture was trained with a 32,000 token context window.23
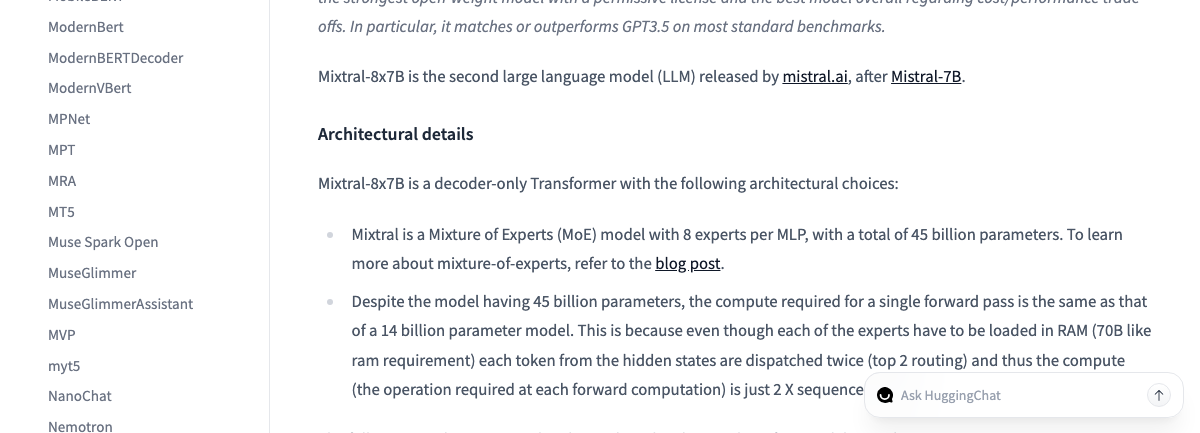
During inference, Mixtral 8x7B routes tokens so that each token accesses only 13 billion active parameters out of its total parameter count.32
Expert parallelism and All-to-All communication
Routing tokens across distributed devices relies on All-to-All communication to reach the assigned targets. Increasing the EP size splits the expert parameter footprint across more nodes, relieving device memory pressure, but it substantially scales All-to-All communication volume across cluster networks. Teams building distributed pipelines alongside tools like Nanotron use specialized dispatchers to keep transfer latencies manageable.45
To prevent communication bottlenecks from stalling compute engines, cluster operators overlap token dispatch with active computation. In MegaScale-MoE, intra-operator overlap reduced training iteration time by 7.1% to 12.9%.16
Production MoE stack comparison
| Stack | Target Model Scale | Primary Optimization | Architectural Focus |
|---|---|---|---|
| MegaScale-MoE | 352B parameters | 1.88x vs Megatron-LM | Intra-operator overlap and 1.41M tokens/s throughput on 1,440 Hoppers |
More on MegaScale-MoE
| |||
| DeepSpeed-MoE | General MoE models | Up to 3.7x size reduction | Novel MoE architecture designs and structural model compression |
More on DeepSpeed-MoE
| |||
| PlaceMoE | Qwen3-VL and DeepSeek-V3 | Up to 6.94x A2A speedup | Replica-gradient synchronization overlapped with attention backward |
More on PlaceMoE
| |||
Configuring Megatron-Core for MoE
The Megatron-Core MoE stack isolates communication domains using Parallel Folding, separating the attention mesh (TP × CP × DP × PP) from the expert mesh (ETP × EP × EDP × PP). To overcome memory walls without sacrificing throughput, engineering teams follow an iterative workflow consisting of freeze the measurement contract, fit, scale, profile, retune, and validate. Hardware configurations should prioritize data parallelism (DP) first, confine hot communication paths within high-speed interconnects, use pipeline parallelism (PP) for multi-node deployments, and prefer EP over extra tensor parallelism (TP) for expert blocks.67
Selective recompute should target specific components such as layernorm, core_attn, moe_act, or mlp, alongside model-specific modules like shared_experts and mla_up_proj. On NVL8 and NVL72 architectures, token dispatcher configurations pair the 'flex' dispatcher with a 'hybridep' backend, or switch to 'deepep' when DeepEP handles exposed transfers. These topologies complement dynamic routing schedulers like TAOT in LoongForge, which uses optimal transport scheduling to cut cross-machine weight transfers, and ForeMoE, which routes recompute transfers through PCIe and policy updates through GPU-direct links.61011