 3AM Marketer
IBM Granite Speech 5.0 Delivers 5.06% WER in New Update
IBM's Granite Speech collection delivers an Apache 2.0 alternative to Whisper, pairing a 5.06% English WER with documented VRAM and runtime profiles across speech models.
IBM released three updates to its Granite Speech collection, introducing the granite-speech-5.0-2b model alongside revised checkpoints for granite-speech-5.0-470m-turboctc and granite-speech-4.1-2b-plus. The granite-speech-5.0-2b release ranks second among top open-weight speech recognition systems with a 5.06% average English word error rate on the Open ASR Leaderboard, trained across 390,000 hours of public audio supplemented by synthetic data.1
For engineering teams deploying local AI models, automatic speech recognition often involves balancing word accuracy against hardware overhead. The release expands beyond English by transcribing French, German, Spanish, Portuguese, and Japanese, while translating to and from English in those languages, as well as handling English translation to Italian and Mandarin.1
Transcription throughput and 19,870 RTFx speeds
Execution latency varies substantially between speech architectures. The granite-speech-5.0-470m-turboctc checkpoint reached 19,870 RTFx on the Open ASR Leaderboard, up from roughly 12,600 RTFx at launch, after compiling a single Conformer block and reusing its graph across the stack. The Turbo CTC model provides multilingual transcription across seven languages: English, Japanese, Spanish, German, French, Italian, and Portuguese.1
By comparison, SenseVoiceSmall uses a non-autoregressive end-to-end architecture supporting Mandarin, Cantonese, English, Japanese, and Korean. At a similar parameter scale, SenseVoiceSmall runs more than 5 times faster than Whisper-Small and 15 times faster than Whisper-Large.2
Keyword biasing lists and 7% diarization gains
Granite Speech 5.0 2B adds keyword biasing support for lists of up to 2,000 terms in every supported language to steer recognition toward product names, people, and acronyms. It also outputs punctuation and capitalization on request, recording capitalization F1 scores between 89.7 and 99.5 across evaluation benchmarks.1
The updated granite-speech-4.1-2b-plus checkpoint focuses on long-form audio and speaker attribution, dropping both its word diarization error rate and speaker-attributed WER by 7%. Its word diarization error rate fell from 4.40 to 4.10, while speaker-attributed transcripts decreased from 30.50 to 28.48 cpWER. Long-form WER dropped from 13.53 to 10.22, average timestamp shift declined from 210.86 to 98.54, and biased-word WER on 20-term lists decreased from 11.79 to 6.48.1
Hardware footprints across speech synthesis models
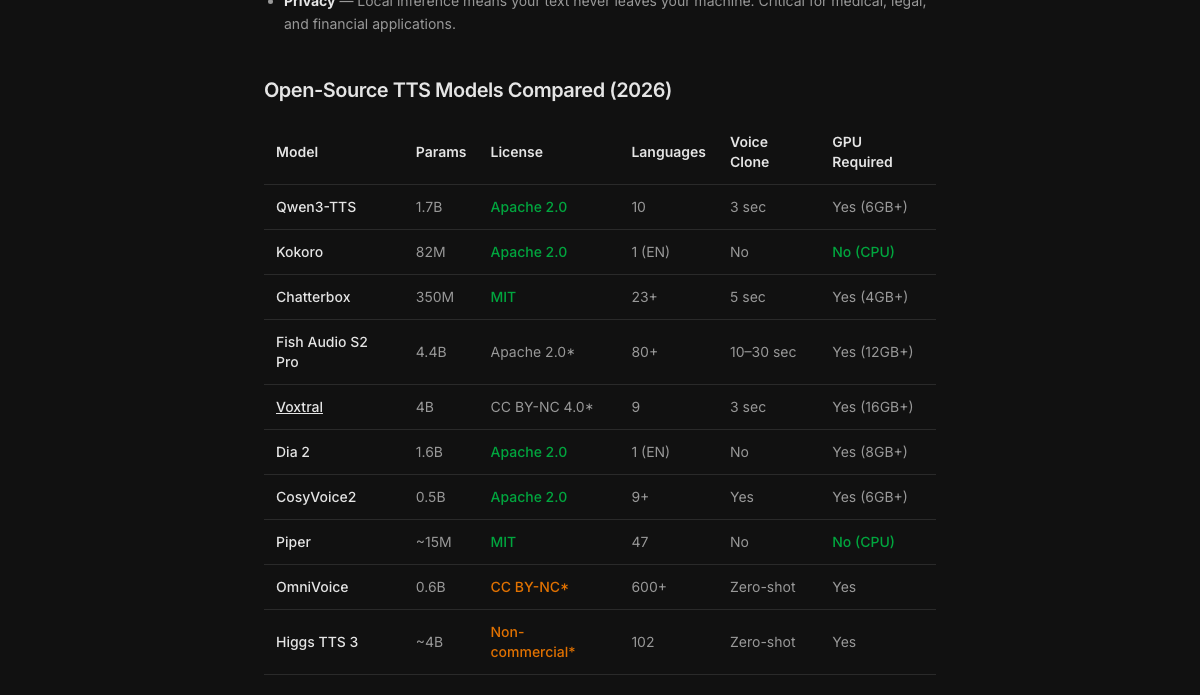
Memory footprints dictate whether a speech pipeline can share an accelerator with self-hosted AI agents or requires dedicated compute.345
| Model | Task | Hardware Minimum | Licence |
|---|---|---|---|
| Kokoro | TTS | CPU only | Apache 2.0 |
More on Kokoro
| |||
| Whisper tiny | ASR | ~1 GB VRAM | MIT |
More on Whisper tiny
| |||
| Whisper small | ASR | ~2 GB VRAM | MIT |
More on Whisper small
| |||
| Whisper medium | ASR | ~5 GB VRAM | MIT |
More on Whisper medium
| |||
| Whisper turbo | ASR | ~6 GB VRAM | MIT |
More on Whisper turbo
| |||
| Whisper large | ASR | ~10 GB VRAM | MIT |
More on Whisper large
| |||
| Qwen3-TTS | TTS | 6 GB+ VRAM | Apache 2.0 |
More on Qwen3-TTS
| |||
| Voxtral | TTS | 16 GB+ VRAM | CC BY-NC 4.0 |
More on Voxtral
| |||
Runtime compatibility and licence terms
Deployment viability often depends on software runtime integration and legal terms. Granite-speech-5.0-2b ships under an Apache 2.0 licence with native support in Transformers, vLLM, llama.cpp, and mlx-audio for Apple Silicon. OpenAI distributes Whisper model weights and codebase under the MIT License.13
In speech synthesis, licensing divides production commercial deployments. Kokoro and Qwen3-TTS run under Apache 2.0, and Bark TTS operates under the MIT licence for commercial use. In contrast, Voxtral enforces a restrictive CC BY-NC 4.0 licence, excluding commercial workflows regardless of available VRAM.45
Teams choosing speech pipelines should audit licensing terms before selecting architectures. When permissive commercial use and structured keyword biasing are required on standard local accelerators, Granite Speech 5.0 and Whisper provide permissive baselines, while non-commercial weights like Voxtral remain restricted to research environments.134