 3AM Marketer
Mistral API Pricing: 2026 Model Token Costs Guide
A complete breakdown of Mistral API pricing across current models, including batch processing discounts and prompt cache rates.
Mistral API pricing ranges from $0.10 per million input tokens on Ministral 3 3B up to $0.70 per million input tokens on Mistral Large 4. Teams running offline workloads can reduce these base rates by 50% using batch endpoints, while repeat prompts benefit from a 10% rate for cached input tokens.123
The current Mistral API pricing structure
Mistral charges for model inference on a per-token basis, separating fees for prompt processing (input) from generation (output). The active catalogue spans small edge-oriented models, mid-tier general models, and flagship reasoning engines tracked in the LLM API pricing timeline.1
The price spread across these tiers is substantial. For 1 million input plus 1 million output tokens, Mistral Ministral 3 3B costs $0.20 and Mistral Large 4 costs $2.80, which is 14 times as much.1
Standard production model costs
The flagship tier recently shifted with the addition of Mistral Large 4 at $0.70 per million input tokens and $2.10 per million output tokens, as documented alongside other Mistral Large 4 release specs. That sits above earlier versions like Mistral Large 3 and mistral-large-2512, which ran at $0.50 input and $1.50 output per million tokens before Mistral retired them.1
| Model | Input ($/1M tokens) | Output ($/1M tokens) | Data Captured |
|---|---|---|---|
| Mistral Large 4 | $0.70 | $2.10 | 2026-11-04 |
More on Mistral Large 4
| |||
| mistral-large-2512 | $0.50 | $1.50 | 2026-10-29 |
More on mistral-large-2512
| |||
| Mistral Large 3 | $0.50 | $1.50 | 2026-10-03 |
More on Mistral Large 3
| |||
| Mistral Medium 3.5 | $1.50 | $7.50 | 2026-10-03 |
More on Mistral Medium 3.5
| |||
| Mistral Small 4 | $0.15 | $0.60 | 2026-10-03 |
More on Mistral Small 4
| |||
| Ministral 3 14B | $0.20 | $0.20 | 2026-10-03 |
More on Ministral 3 14B
| |||
| Ministral 3 8B | $0.15 | $0.15 | 2026-10-03 |
More on Ministral 3 8B
| |||
| Ministral 3 3B | $0.10 | $0.10 | 2026-10-03 |
More on Ministral 3 3B
| |||
Operational cost-saving strategies
Mistral provides two native mechanisms to lower inference expenses on production applications: asynchronous batching and prompt caching.23
Batch processing allows running asynchronous inference on large inputs in parallel at a 50% discount. Cached tokens in the chat completion endpoint are billed at 10% of the standard input token price, reducing repetitive system prompt overhead.23
Technical requirements for batch processing
Taking advantage of the 50% batch discount requires routing jobs through specific payload limits. The batch processing service supports up to 1 million requests in a single batch file.3
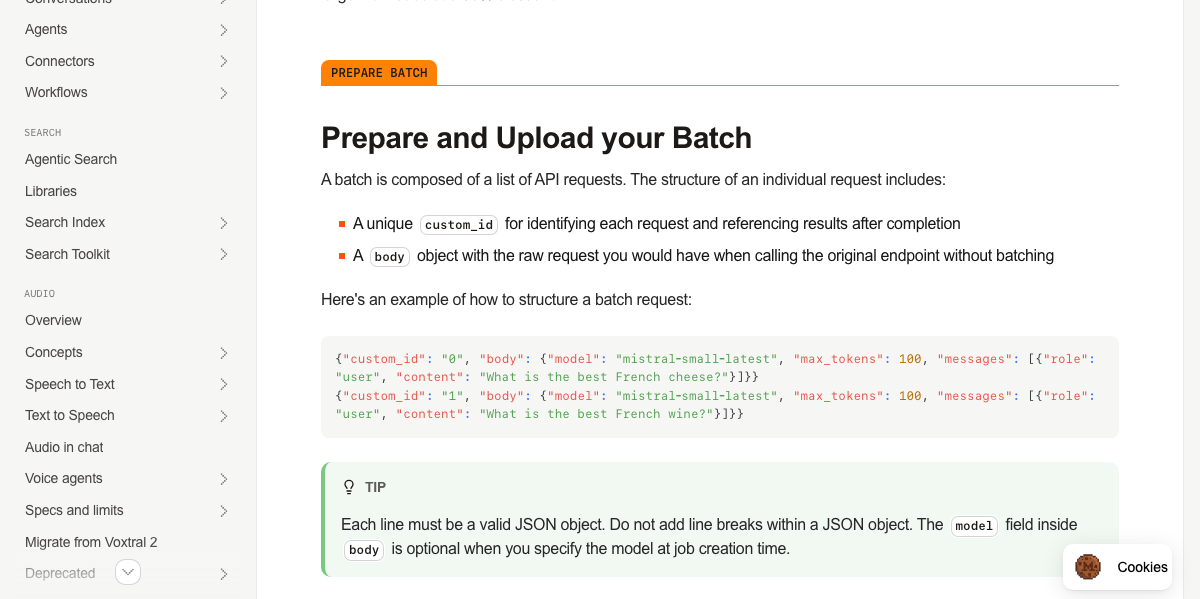
For lighter bulk queues, teams do not need to generate and upload dedicated file objects. Inline batching is supported for batches containing fewer than 10,000 requests, allowing developers to include the request body directly in the call.3
What we got wrong
Our pricing tracker records Medium 3.5 and Large 3 as removed from Mistral's pricing pages; Mistral's model page lists Large 4 at $0.70 per million input tokens and $2.10 per million output tokens.