 3AM Marketer
DeepSeek API Pricing: V4.1 Rates, Cache, and Limits
A technical breakdown of DeepSeek API pricing across peak and off-peak cycles, prompt cache rates, and operational concurrency limits.
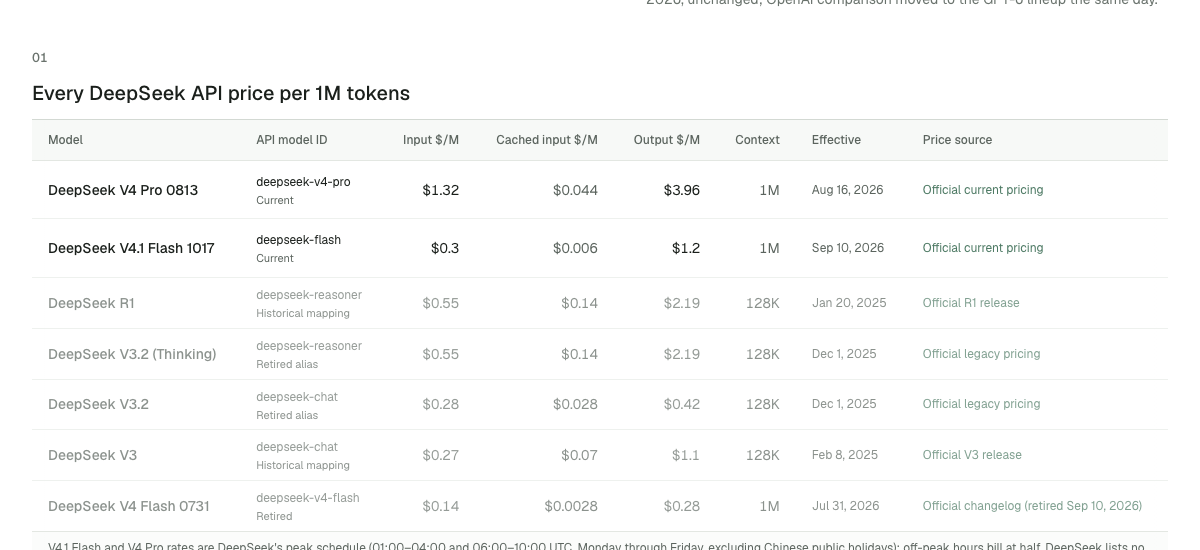
DeepSeek API token pricing ranges from $0.15 to $1.32 per million input tokens and $0.60 to $3.96 per million output tokens, governed strictly by peak cycles and model tiers. Peak hours double the base token rates across both primary endpoints, while prompt cache hits reduce input expenses down to fractions of a cent.12
Active models: DeepSeek-V4.1-Flash and V4-Pro
Production API traffic routes through two active identifiers: deepseek-flash and deepseek-v4-pro. DeepSeek documentation confirms that legacy names like deepseek-v4-flash and deepseek-v4-flash-vision-exp have been retired. Developers building high-throughput pipelines or tracking LLM API pricing timeline metrics should configure the active designations directly.134
According to our open-weight LLM release records, DeepSeek-V4.1-Flash-1017 launched on October 17, 2026, with 763.2B parameters under an MIT licence, following the original V4.1 Flash release on September 10, 2026. The larger DeepSeek-V4-Pro released on August 13, 2026, scaling to 1650.5B parameters under the same MIT licence, up from the 1598.8B parameter DeepSeek-V4-Pro model released on April 22, 2026.5
Peak versus off-peak billing across tiers
Token fees depend on query timing: published rate sheets show that peak pricing is exactly double the off-peak rate across both models. DeepSeek-V4.1-Flash-1017 charges $0.30 per million standard input tokens and $1.20 per million output tokens during peak hours, dropping to $0.15 for input and $0.60 for output during off-peak periods. Any reasoning tokens generated during execution are billed at standard output token rates rather than lower input tiers.12
For the larger DeepSeek-V4-Pro endpoint, standard input costs $1.32 per million tokens during peak hours and output costs $3.96 per million tokens. Our price records from October 3, 2026, show that processing a combined workload of 1 million input tokens and 1 million output tokens costs $1.50 on deepseek-flash versus $5.28 on deepseek-v4-pro, making the Pro tier 3.5 times as expensive as Flash under peak rates.14
Prompt cache pricing and hit tracking
As with Claude prompt caching, cache hits sharply cut the cost of repetitive context and system instructions. During peak hours, cached input for DeepSeek-V4.1-Flash-1017 drops from $0.30 to $0.006 per million tokens, while off-peak cache hits fall to $0.003 per million.12
On DeepSeek-V4-Pro, peak cached input costs $0.044 per million tokens compared to the standard $1.32 cache-miss rate. Developers can audit these savings at runtime because DeepSeek exposes prompt_cache_hit_tokens and prompt_cache_miss_tokens directly within the usage object of every API response.1
Concurrency limits and Web Search fees
Throughput architectures must account for account-level limits alongside raw token prices. DeepSeek sets account-level concurrency limits at 2,500 requests for V4.1 Flash and 500 requests for V4 Pro.1
In addition to core inference endpoints, DeepSeek offers standalone Web Search and Fetch APIs. Effective November 1, 2026, web Search and Fetch APIs are billed at $0.75 per 1,000 successful requests each, providing structured internet retrieval capabilities without requiring third-party scraping infrastructure.1