 3AM Marketer
Best LLM for 16GB VRAM: 14B Sweet Spot and Specs
A hardware-matched evaluation of the best local LLMs for 16GB VRAM, comparing 8B, 14B, and 27B models across throughput, KV cache scaling, and API costs.
For a 16GB VRAM GPU, 14-billion parameter models provide the best operational balance between reasoning capability and raw throughput. While an 8B or 9B model delivers low latency and a squeezed 27B model fits only with narrow context windows, 14B architectures sit entirely in memory with enough headroom for active inference.123
Understanding hardware requirements in our local AI models guide comes down to memory budgeting: model weights, runtime buffers, and the KV cache all contest the same frame buffer boundary. When configuring local serving stacks, engineers evaluating vLLM vs Ollama concurrency or exploring standalone Ollama alternatives rely on llama.cpp to shrink tensor footprints using 1.5-bit, 2-bit, 3-bit, 4-bit, 5-bit, 6-bit, and 8-bit integer quantization.4
Which LLM should you run on 16GB VRAM?
The choice on a 16GB card divides into three specific operational tiers depending on the task: high-speed interactive generation, general-purpose reasoning, or constrained large-model execution. For fast responses, Llama 3.1 8B and Qwen 3.5 9B run at Q8_0 precision or unquantized without saturating capacity. For coding and multi-turn workflows, Qwen 3 14B and DeepSeek R1 Distill 14B occupy the sweet spot between memory consumption and accuracy.125
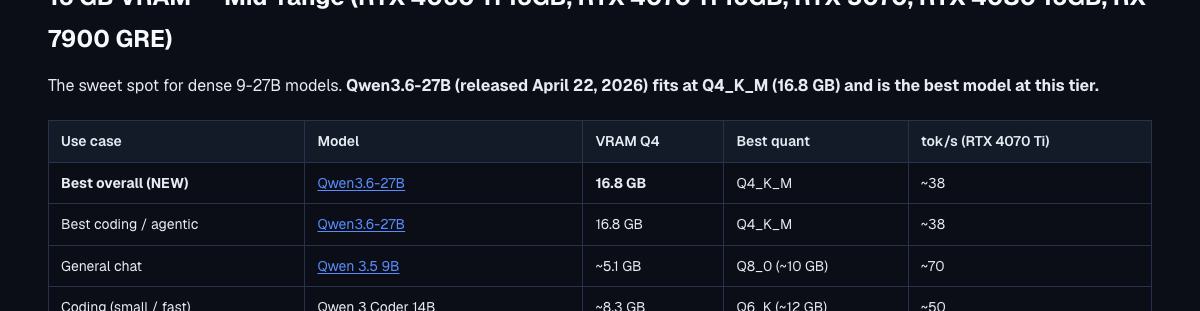
A 16GB frame buffer runs Qwen 3.5 27B dense at Q4_K_M consuming approximately 16GB, Qwen 3.5 9B at Q8_0 utilizing around 10GB with long context, Llama 3.1 8B at Q8, and Qwen 3 14B at Q8. Pushing into 27B models yields higher output quality per token, but eliminates the memory buffer required for long document processing.2
Why 14B models hit the 16GB sweet spot
Mid-sized 14B checkpoints deliver sufficient depth for technical workloads without causing out-of-memory errors. Uncompressed BF16 safetensors weights for Qwen2.5-14B-Instruct total 29,540,181,472 bytes across 14.7 billion total parameters and 13.1 billion non-embedding parameters spanning 48 layers. It implements Grouped Query Attention with 40 query heads and 8 key-value heads, supporting a full context length of 131,072 tokens and 8,192 generation tokens.6
When quantized, Qwen3 14B sits comfortably in 12GB of VRAM and runs at around 61 tokens per second, leaving 4GB available for context expansion. In code generation tasks, Qwen 3 Coder 14B requires approximately 8.3GB of VRAM at Q4 and 12GB at Q6_K, achieving around 50 tokens per second on an RTX 4070 Ti. On an RTX 4060 Ti 16GB, Qwen 3 14B at Q4_K_M generates 35 tokens per second.12
Specialized reasoning variants also align cleanly within this envelope. DeepSeek R1 Distill 14B uses approximately 8GB of VRAM and achieves 60 tokens per second at Q5_K_M on an RTX 4070 Ti. For even lighter footprints, Gemma 3 12B QAT requires around 6.6GB of VRAM in INT4 precision.25
| Model | Quantization | VRAM Footprint | RTX 4070 Ti Speed | RTX 4060 Ti Speed |
|---|---|---|---|---|
| Llama 3.1 8B | Q4 | ~4.6 GB | ~80 tok/s | Not listed |
More on Llama 3.1 8B
| ||||
| Llama 3.1 8B | Q8_0 | ~8 GB | ~80 tok/s | Not listed |
More on Llama 3.1 8B
| ||||
| Llama 3.1 8B | FP16 | ~16 GB | Not listed | Not listed |
More on Llama 3.1 8B
| ||||
| Qwen 3.5 9B | Q4_K_M | ~5.1 GB | ~70 tok/s | 50 tok/s |
More on Qwen 3.5 9B
| ||||
| Qwen 3.5 9B | Q8_0 | ~10 GB | ~70 tok/s | Not listed |
More on Qwen 3.5 9B
| ||||
| Qwen 3 14B | Q4_K_M | Within 12 GB | 55 tok/s | 35 tok/s |
More on Qwen 3 14B
| ||||
| Qwen 3 Coder 14B | Q4 | ~8.3 GB | ~50 tok/s | Not listed |
More on Qwen 3 Coder 14B
| ||||
| Qwen 3 Coder 14B | Q6_K | ~12 GB | ~50 tok/s | Not listed |
More on Qwen 3 Coder 14B
| ||||
| DeepSeek R1 Distill 14B | Q5_K_M | ~8 GB | ~60 tok/s | Not listed |
More on DeepSeek R1 Distill 14B
| ||||
| Gemma 3 12B QAT | INT4 | ~6.6 GB | Not listed | Not listed |
More on Gemma 3 12B QAT
| ||||
| Qwen 3.5 27B | Q4_K_M | ~16 GB | ~38 tok/s | Not listed |
More on Qwen 3.5 27B
| ||||
High-precision 8B and 9B models for low-latency tasks
Deploying 8B and 9B weights eliminates memory bottlenecks entirely and unlocks sustained interactive generation rates. For a standard 7B model, Q4_K_M quantization occupies roughly 5GB of VRAM compared to 14GB at full precision. Moving to dense configurations, the uncompressed BF16 safetensors files for google/gemma-2-9b-it total 18,483,505,520 bytes across 9,241,705,984 parameters.17
Llama 3.1 8B Instruct requires approximately 16GB of VRAM when run unquantized in FP16, representing a tight fit on consumer hardware. At Q4 quantization it requires roughly 4.6GB, and at Q8_0 it takes about 8GB, reaching around 80 tokens per second on an RTX 4070 Ti.25
Similarly, Qwen 3.5 9B requires roughly 5.1GB of VRAM at Q4 and approximately 10GB at Q8_0, generating ~70 tokens per second on an RTX 4070 Ti. On an RTX 4060 Ti 16GB card, Qwen 3.5 9B at Q4_K_M generates 50 tokens per second. In addition, DeepSeek-R1-Distill-Qwen-7B runs comfortably at 4-bit quantization with approximately 4.5GB of VRAM.25
The 27B squeeze: KV cache scaling and layer offloading
Attempting to run 27B parameter models on a 16GB card pushes memory allocation to the hardware limit. On an RTX 4070 Ti, Qwen 3.5 27B at Q4_K_M operates tightly at approximately 16GB of VRAM with an output speed of ~38 tokens per second. Understanding these constraints is essential when sizing local runtimes for larger models without causing out-of-memory faults.2
When autoconfiguring layer offloading to the GPU, llama.cpp tries to maintain 1GB of free VRAM. As context extends from 19K to 32K or 64K tokens, KV cache growth increases VRAM pressure. This cache expansion forces the engine to offload fewer layers to the GPU, degrading execution speed across long prompts.3
Documented benchmarks on an RTX 4080 running Qwen3.5-27B-IQ4_XS.gguf confirm the steep performance cliff: running with 18k context and 65 layers achieved 38.0 tokens per second, but expanding to 64k context dropped GPU layers to 53 and slowed generation speed to 15.7 tokens per second.3
Comparing local 16GB hardware against API hosted tokens
Running weights locally removes per-token billing, but commercial endpoints demonstrate distinct pricing across these exact parameter classes. From our data, hosted qwen3.5-27b costs $0.30 input and $2.40 output per million tokens, captured on 2026-10-10. For mid-tier weights, qwen3-14b costs $0.35 input and $1.40 output per million tokens, captured on 2026-10-13.8
Small distilled models operate at fractions of full reasoning pricing. From our data, hosted deepseek-r1-distill-qwen-7b costs $0.072 input and $0.144 output per million tokens, whereas hosted deepseek-r1 reaches $0.574 input and $2.294 output per million tokens, captured on 2026-10-13. For 1 million input plus 1 million output tokens, deepseek-r1-distill-qwen-7b costs $0.216, while deepseek-r1 costs $2.868, which is 13.3 times as much.8
For interactive workflows on a 16GB card, deploy Qwen 3 14B or DeepSeek R1 Distill 14B at Q5_K_M or Q6_K to retain prompt context without triggering CPU offloading. Switch to an 8B model at Q8_0 if sustained generation must exceed 70 tokens per second, and reserve 27B Q4 execution strictly for short prompts under 18k tokens.123