 3AM Marketer
NVIDIA Nemotron 3.5 Bolt: 256K Context, 25GB Local Model
NVIDIA has released Nemotron 3.5 Bolt, a compact vision-language model for local coding, reasoning, and tool use featuring E4B and 74B-A9B architectures.
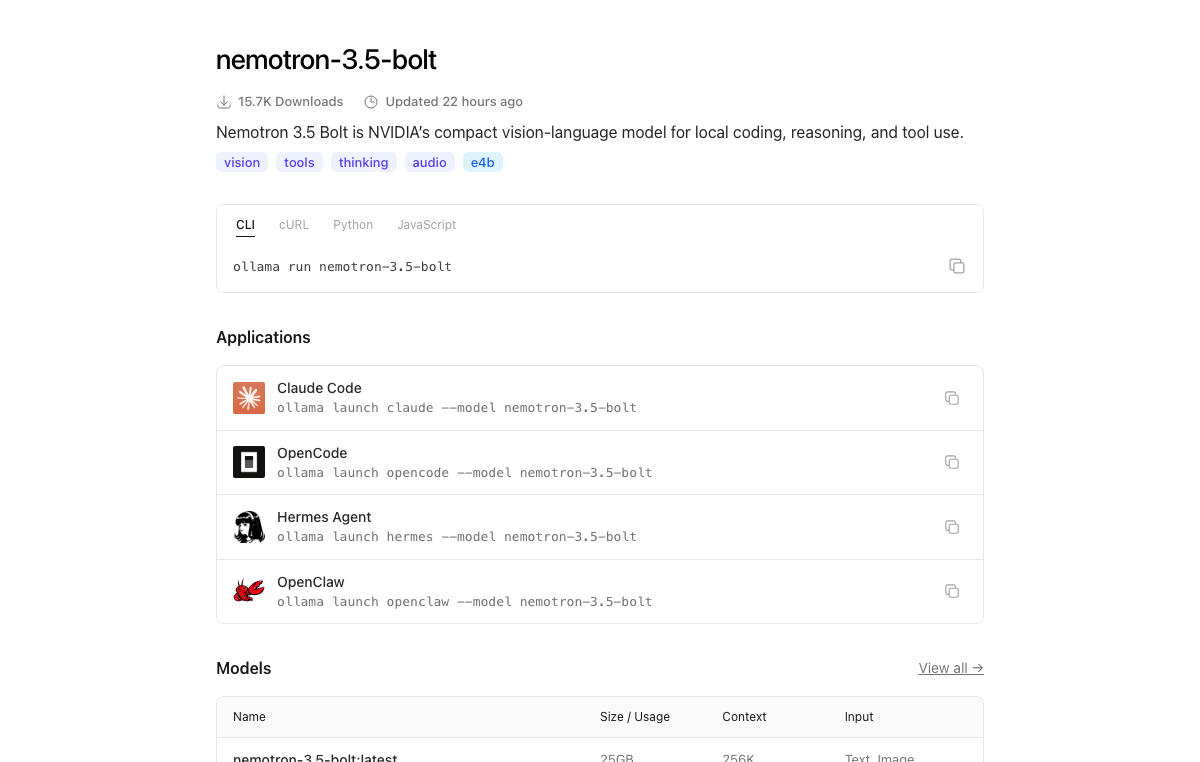
NVIDIA launched Nemotron 3.5 Bolt as a compact local vision language model built for local coding, reasoning, and tool use, requiring 25GB of storage and featuring a 256K context window for its latest build. The release introduces two primary deployment pathways, separating smaller desktop hardware from larger multi-accelerator configurations.1
Understanding the Nemotron 3.5 Bolt architecture
The 74B-A9B variant uses a hybrid structural design, combining a Mamba-2/Transformer mixture-of-experts backbone with a C-RADIO vision encoder. It maintains 74 billion total parameters while activating 9 billion parameters per token during processing, reducing active compute overhead while retaining full parameter capacity across text and image tasks.1
By incorporating the C-RADIO vision encoder directly into the Mamba-2 hybrid backbone, the architecture processes multimodal input feeds within its mixture-of-experts structure. For engineers evaluating multimodal AI app architectures, this design balances memory footprint and reasoning throughput during multimodal token generation.1
Variant comparison: E4B vs 74B-A9B
Hardware compatibility sharply divides the Nemotron 3.5 Bolt family. The compact E4B model is post-trained from Gemma 4 E4B, packaging 8 billion total parameters with 4 billion effective parameters. In contrast, the larger 74B-A9B model targets server-grade inference and lacks support on Apple Silicon and Metal platforms.1
| Variant | Total Parameters | Active / Effective Parameters | Context Window | Storage Footprint | Supported Platforms |
|---|---|---|---|---|---|
| nemotron-3.5-bolt:e4b | 8B | 4B effective | 128K | 7.2GB - 7.9GB | Windows, Linux, Apple Silicon |
More on nemotron-3.5-bolt:e4b
| |||||
| nemotron-3.5-bolt:74b-a9b | 74B | 9B active per token | 256K | 25GB (base latest) | Windows, Linux (No Apple Silicon / Metal) |
More on nemotron-3.5-bolt:74b-a9b
| |||||
Teams deploying on consumer workstations can review local AI model hardware requirements to size memory channels, as the E4B build operates within 7.2GB to 7.9GB of storage and handles a 128K context window across Windows, Linux, and Apple Silicon environments.1
Optimization and quantization techniques
NVIDIA created Bolt by compressing Nemotron 3.5 Super through further training and quantization-aware distillation. The published GGUF implementation applies IQ2_XXS quantization specifically to expert weights while preserving precision by assigning NVFP4 and Q8_0 formats across the remaining network layers.1
All Nemotron 3.5 Bolt releases are governed under the OpenMDW License Agreement, version 1.1. According to 3AM Marketer tracking data on the open model release tracker, NVIDIA has standardized on the openmdw-1.1 license across its recent open model releases.13
Implementing local tool use and reasoning
Nemotron 3.5 Bolt natively supports multi-turn tool calling, permitting developers to execute functions and ingest operational responses across prolonged execution loops. When building with local runtimes like Ollama, the model calls functions and incorporates their results directly across multi-turn tasks via the documented runtime API.12
Developers can also toggle a thinking feature on or off to dictate model behavior. Enabling thinking prompts the model to execute explicit reasoning steps before returning its final answer.1